Your work is scattered across notes and chats
AI proposes candidates from sessions you select. Read the quotes, confirm your contribution, and approve a card you can reuse.
A product by SH Ryu Studio
Early beta · For Claude Code, Codex and OMP users
AI proposes candidates you may have forgotten, with quotes from permitted Claude Code, Codex or OMP sessions. Approve claims, then draft job-tailored lines. Detected unsupported numbers, names or tools block approval; checks can miss them.
 Play the 95-second demo
AI proposes candidates from sessions you select. Read the quotes, confirm your contribution, and approve a card you can reuse.
AI numbers, names and tools must appear in cited approved claims. Matching words cannot prove truth; check the sentence's meaning and your contribution yourself.
Access is not permission to retain, process or send a session. If permission is unclear, do not read it; use a separately permitted retrospective instead.
Select and check sessions locally. Review the send summary, open the full content to read it, then explicitly confirm each AI send.
First run: about 30–40 minutes from reading the guide to drafting application text from your logs. Modelled, not yet measured with people; not the synthetic rehearsal alone.
Choose Claude Code, Codex or OMP sessions and dates. First confirm permission to retain/process them and whether they came from a company device or account.
Local filtering keeps your prompts and final answers and drops file, diff, tool-output blocks and reasoning. Text pasted into a prompt can remain, so read the preview.
Checks cover deny terms, amounts, issue IDs, internal hosts, emails, phones, secrets, paths, retractions and contradictions. Review target, account, size, risk flags and hash; open the full content before confirming.
Read each candidate with quotes from the text actually sent. A quote is not proof of truth; limited evidence may yield fewer candidates or none.
Edit to separate your role from AI and team contributions. Review the diff, then approve confirmed claims and their exact sharing scope yourself.
Add minimal career facts and one job description. Preview and confirm sending approved claims plus permitted requirements and target role. AI proposes résumé lines, interview answers and job-tailored text.
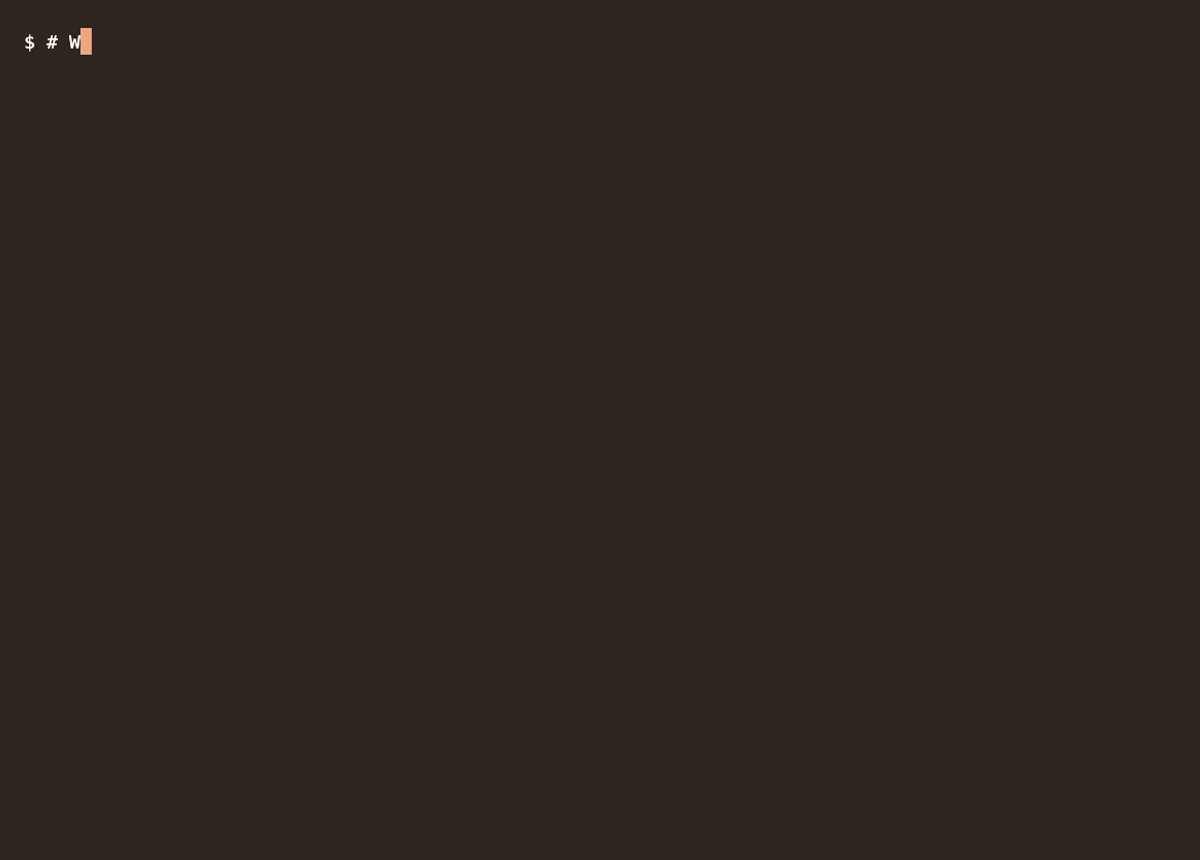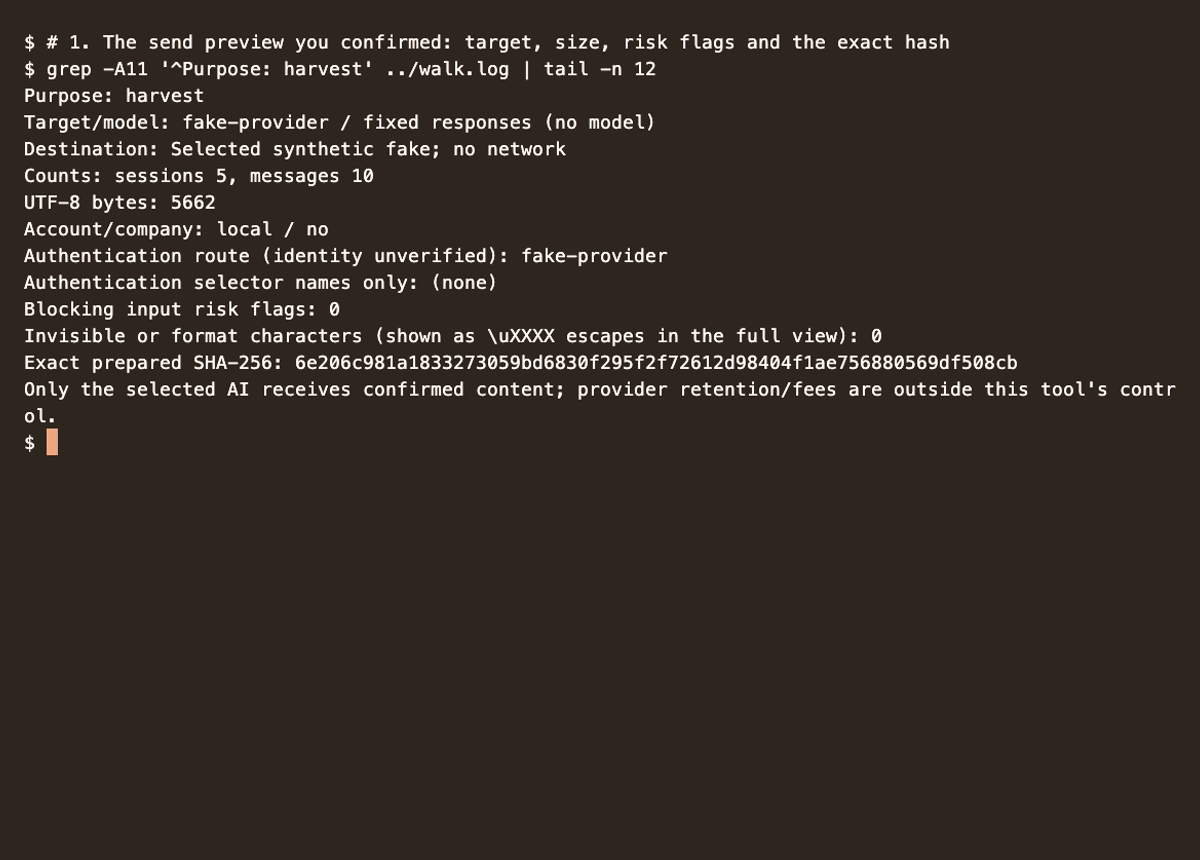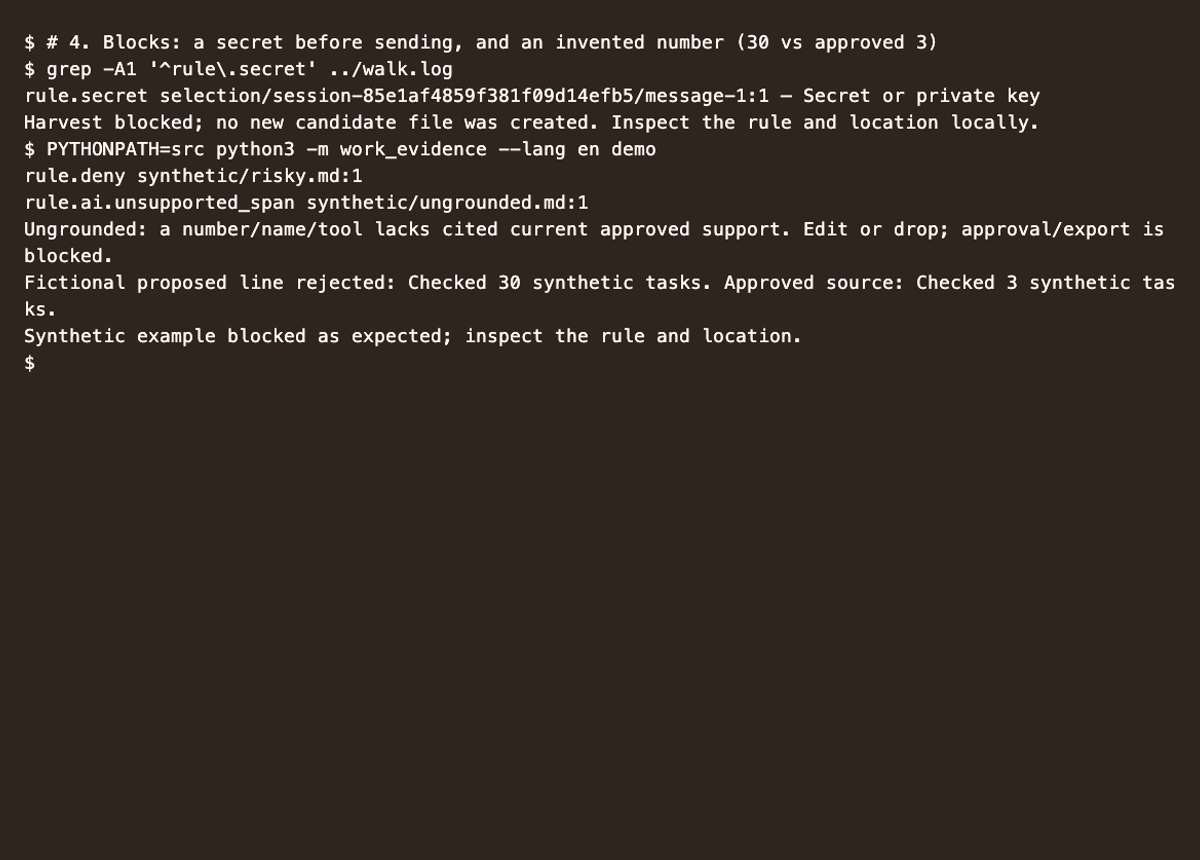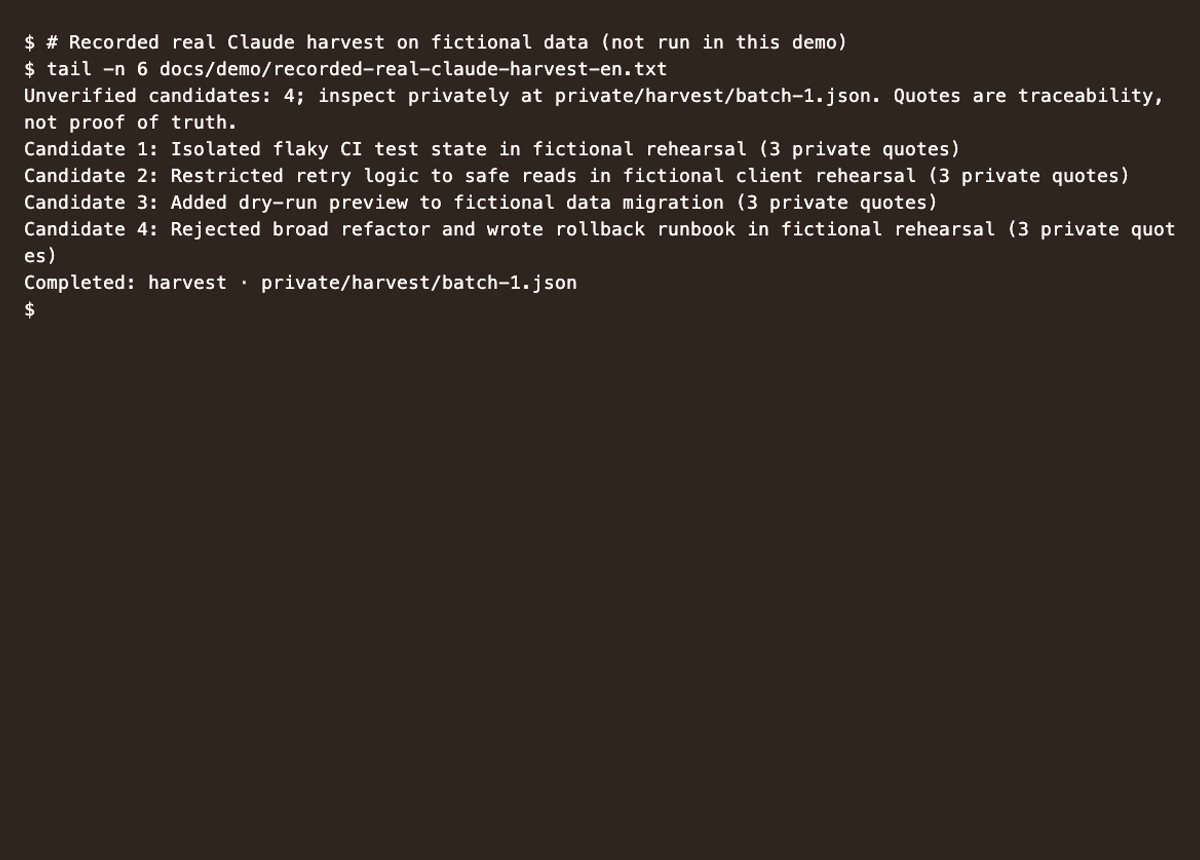
If the claim says “Checked 3 sample tasks” but AI writes “30,” the line is blocked. Detected unsupported numbers, names or tools prevent approval; missed expressions still need human review.
Edit and approve each AI sentence, then re-check the final files. Explicit export approval saves Markdown text files. Applying, publishing or sharing is your separate action.
Assemble and check the text you approve, then save Markdown files. Session quotes stay private. This does not write your complete résumé.
Fictional data, real Claude Code runs. Korean candidate cards are actual Korean output. Résumé lines and human-edited blocked lines are English output with Korean explanations, not real achievements.
One real run on fictional data; results vary between runs. Four candidates: continuous integration (CI) failures 9/50 → 0/50, safe-read retries, migration preview, and a narrow repair with rollback. Each shows two of its three quotes; AI-only work was not proposed. Check facts and your contribution.
    quote:   "I isolated shared test state and rejected hiding the flaky test behind retries."
    quote:   "I verified CI failures fell from 9 of 50 runs to 0 of 50 runs after isolating test state in the synthetic exercise."
    quote:   "AI proposed retrying every request; I reviewed the proposal and restricted it to safe reads."
    quote:   "I verified the synthetic client retried transient read failures and did not repeat writes in the controlled tests."
    quote:   "I designed a migration dry-run and kept the original synthetic records unchanged until reviewing the preview."
    quote:   "I verified a dry-run left the synthetic input unchanged and that a reviewed migration handled missing fields."
    quote:   "I rejected the broad refactor, kept the narrow repair and wrote a runbook explaining the rollback decision."
    quote:   "I verified the narrow repair with controlled tests and checked the rollback steps against synthetic data."
The real English AI résumé draft describes isolating test state instead of hiding failures with retries, and CI failures falling from 9/50 to 0/50 in a synthetic exercise. Both lines cite approved claims; review still comes before approval.
  [resume] Isolated shared test state causing a flaky test, rejecting the option to hide it behind retries.   <- sample-card/isolation
  [resume] In a synthetic exercise, verified that isolating test state reduced CI failures from 9 of 50 runs to 0 of 50 runs.   <- sample-card/ci-results
Job-description requirements and evidence
A reviewer added “across 12 repositories” or sentence-initial “Kubernetes” to the real English AI interview draft. Both edits were blocked as unsupported and could not be approved/exported. These two checks do not establish complete detection.
# Human edits one interview line (invented tool at sentence start): Kubernetes when I encountered a flaky test, I isolated the shared test state behind it rather than masking the problem with retries.
AI line 3: ungrounded
rule.ai.unsupported_span ai/span:1 — Unsupported number/name/tool
Ungrounded: a number/name/tool lacks cited current approved support. Edit or drop; approval/export is blocked.
[exit 3]
# Human edits one interview line (invented number): When I encountered a flaky test, I isolated the shared test state behind it rather than masking the problem with retries across 12 repositories.
AI line 3: ungrounded
rule.ai.unsupported_span ai/span:1 — Unsupported number/name/tool
Ungrounded: a number/name/tool lacks cited current approved support. Edit or drop; approval/export is blocked.
[exit 3]
AI proposes candidates and wording; you confirm facts, contribution and scope. Supported numbers, names and tools do not prove the sentence's meaning. A complete manual path works without AI too.
Check permission before reading and run checks before sending. The summary shows target, account, size, risk flags and the full payload's hash. Open the full content and confirm each send; the summary cannot establish confidentiality.
Use a local model or the same command-line tool and account that produced the logs. Remote AI can use the network; only the manual fallback completes without it.
Checks can miss sensitive details or unsupported meaning. Reading, AI sending and sharing need separate permission; a passed check or same account grants none.
Grounding checks can miss some lowercase tool names and Korean-script names. Supported numbers, names or tools do not prove meaning or your contribution. Before approval, read every line for invented facts.
Choose a supported Claude Code CLI version or an existing local Ollama model. Codex logs can be read, but Codex sending is disabled until isolation is proven. If isolation cannot be confirmed, sending stops; choose a local/manual path. An application programming interface (API) is optional. No automatic install, sign-in or switch.
Setup asks whether logs came from a company device or account. Yes or unknown restricts sending to a local model or the same producing tool/account. “Same account” is your attestation, not automatic authentication.
For company or unknown-origin logs, a different or unknown account requires typing the specified authority phrase interactively. This is not legal clearance or a check bypass; preview and send confirmation still apply.
Harvest filtering drops file, diff and tool-output blocks from prompts/final answers. Pasted prompt text can remain; read the preview. Caps are 16,384 UTF-8 bytes/session and 49,152 per complete send. Overflow is blocked, not truncated.
Claude Code deletes local transcripts after 30 days by default; actual settings may differ. Check the oldest available date and run a manual harvest weekly. This tool does not change agent settings.
The tool cannot know your employment contract or company rules. Confirm permission to retain, process, send and share.
Removing names may not hide a company identifiable from combined facts. Pattern checks cannot decide confidentiality; do not send or share uncertain content.
This early beta is for command-line interface (CLI) coding-agent users with permission to process local logs: Claude Code, Codex or oh-my-pi (OMP). You must review AI suggestions and distinguish your contribution.
Web-chat-only users are not yet supported; export importers are later scope. No background harvesting, company-system integrations or automatic applications.
Try the synthetic example first. Do not use real company material in the walkthrough.
You need Python 3.9+, a terminal and a source copy. AI needs a supported CLI version or existing model/account. Unconfirmed isolation blocks sending; choose an authorised local/manual path.
From the source folder, open help and rehearse with fictional sessions and fake responses, without sending to your chosen AI. See the real Claude output above.
PYTHONPATH=src python3 -m work_evidence --lang en --helppython3 examples/synthetic/sessions/walkthrough.py --lang en --data-dir ../synthetic-ai-enPYTHONPATH=src python3 -m work_evidence --lang en init --data-dir ~/work-evidence-dataKeep data outside the source folder. Setup asks permission, company context and AI choice; it does not install providers or sign in for you.
This early beta proposes quote-backed candidates from permitted sessions and AI text from approved claims. Human review, approval and checks precede Markdown export. The manual path remains.
Web-chat importers, background harvesting, company integrations, sync, dashboards, automatic applications and hiring-success scores are outside this round.
The source code is public on GitHub. See the licence at the bottom of this page.
Selected remote AI can receive content after permission and local checks. Preview the target, account, size, risk flags and full-content hash; open the full view and confirm each send. Company-origin account restrictions apply. Manual mode makes no network requests.
The primary discovery and drafting path needs your chosen AI. If AI is unavailable or not permitted, complete the manual path: write a five-prompt retrospective, card and application text, then check and approve them.
This early beta has no paid features. Your chosen AI's fees, latency and retention depend on the provider or local setup; this tool does not control them.
No. Checks help find expressions matching your configured rules and can miss sensitive details. Confirm company permission yourself; if unclear, do not collect or share.
Python 3.9 or newer is required, but this beta's Windows workflow has not yet been verified. A Windows guide depends on the verification results.
Use GitHub Issues or the studio email. Issues are public. Do not send company material, real work cases, personal data or private files.
This site collects no personal data: no forms, cookies, analytics or trackers.